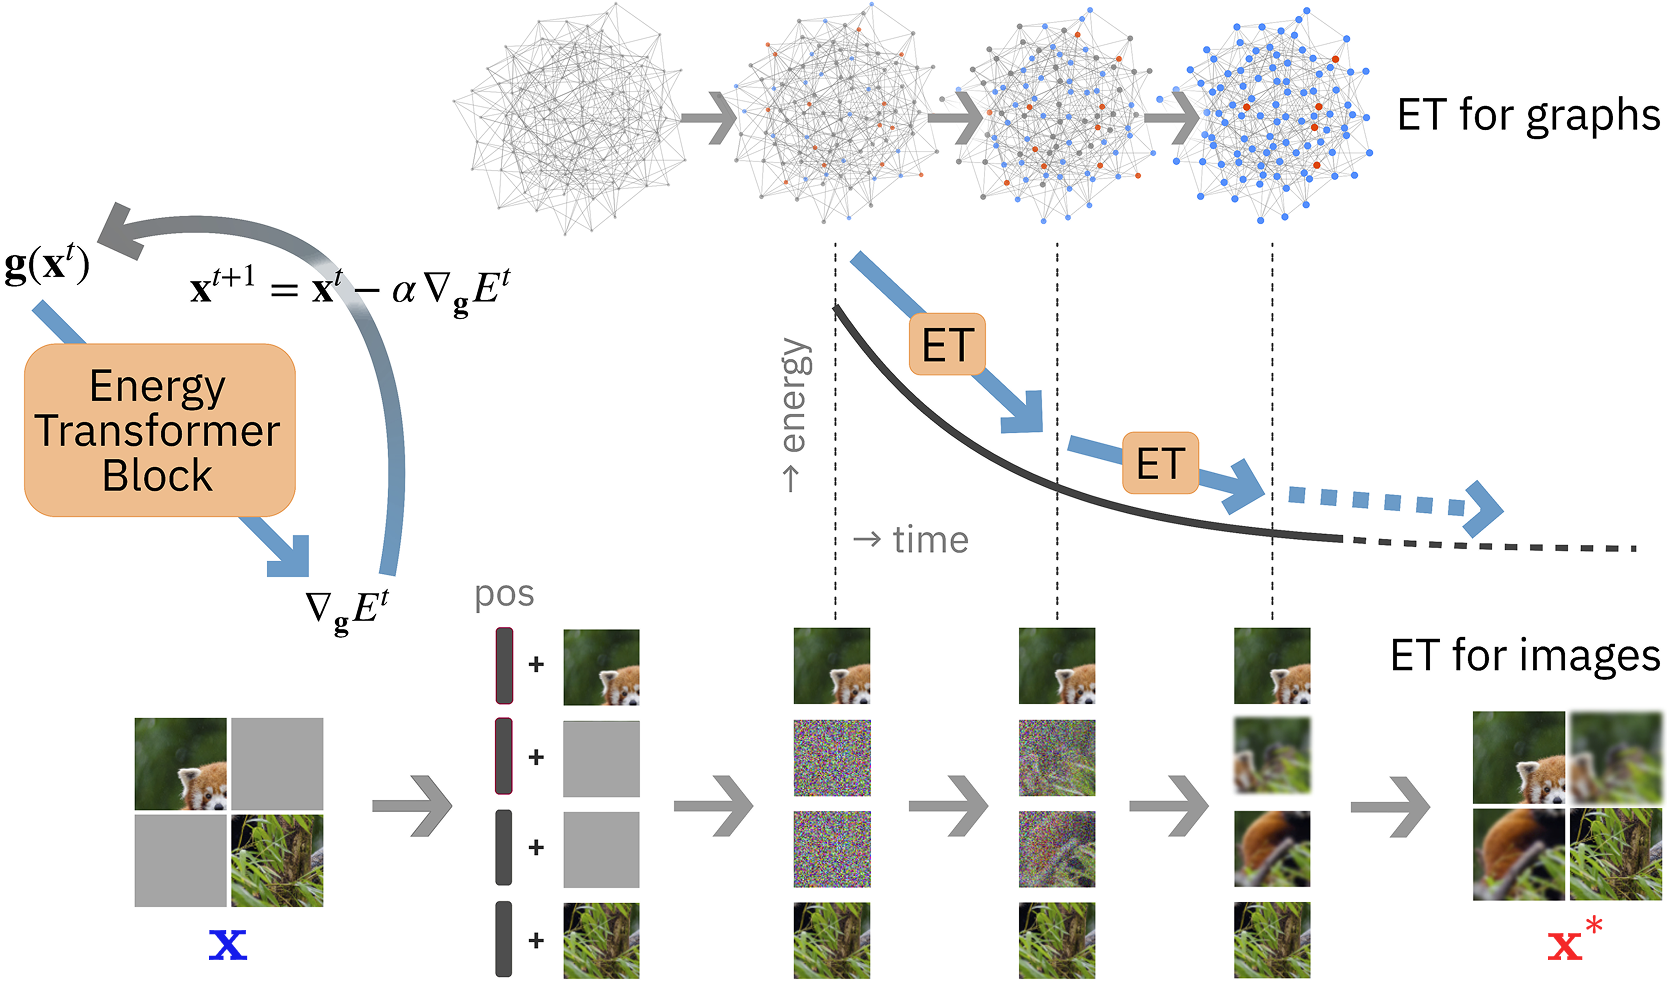
Our work combines aspects of three promising paradigms in machine learning, namely, attention mechanism, energy-based models, and associative memory. Attention is the power-house driving modern deep learning successes, but it lacks clear theoretical foundations. Energy-based models allow a principled approach to discriminative and generative tasks, but the design of the energy functional is not straightforward. At the same time, Dense Associative Memory models or Modern Hopfield Networks have a well-established theoretical foundation, and allow an intuitive design of the energy function. We propose a novel architecture, called the Energy Transformer (or ET for short), that uses a sequence of attention layers that are purposely designed to minimize a specifically engineered energy function, which is responsible for representing the relationships between the tokens. In this work, we introduce the theoretical foundations of ET, explore its empirical capabilities using the image completion task, and obtain strong quantitative results on the graph anomaly detection and graph classification tasks.
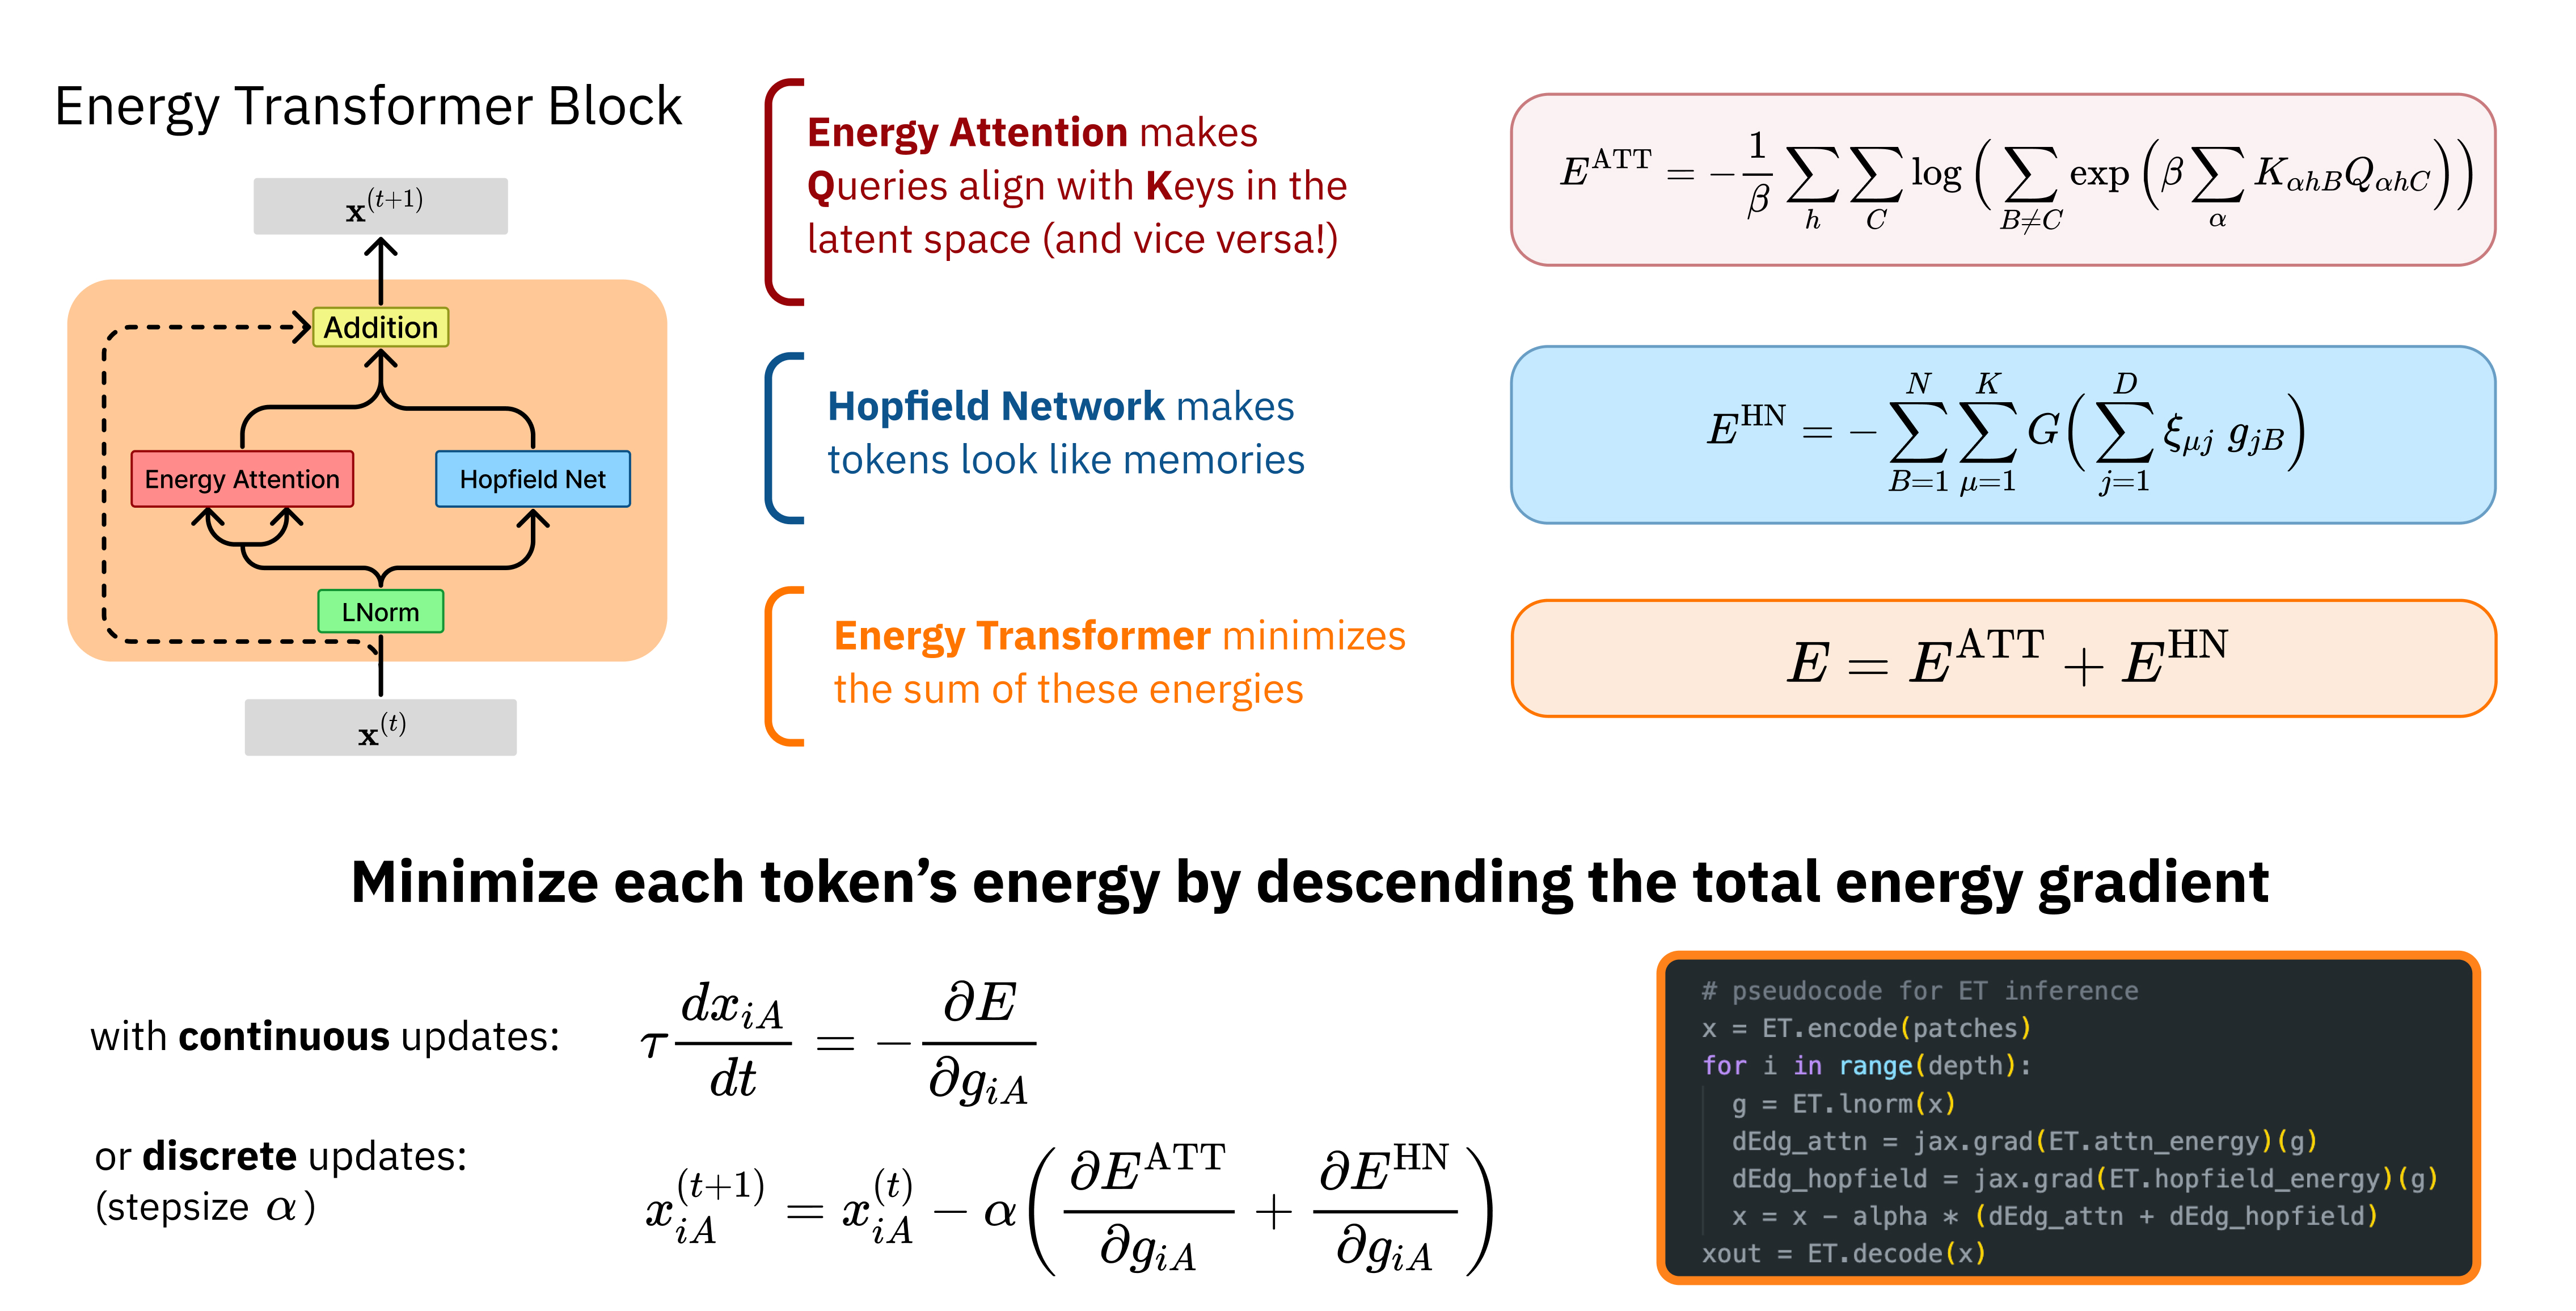
A single block holds two modules that read the same layer-normalized tokens. Energy Attention contributes a term that is low when queries align with keys, so attention here is not a hand-designed operation but a sum in the energy across all attention heads and positions. The Hopfield Network contributes a second term that is low when tokens resemble the stored memory vectors, which is what makes the tokens behave like memories. Their sum, \(E = E^{\text{ATT}} + E^{\text{HN}}\), is the entire objective, and the block updates the tokens by descending its gradient, either in continuous time or in discrete steps of size \(\alpha\). Because both terms are differentiable scalars, the resulting implementation is short: the update is nothing more than automatic differentiation of the energy.
Because every update is the gradient of an energy, the contribution of each module can be decoded back into the input space and simply looked at. The figure follows one image completion across the descent, where at each step the token state receives a Hopfield Network update and an Energy Attention update, and each can be rendered on its own. Early in the descent the two updates are large and coarse as they rough in the masked patches. Late in the descent they have shrunk and the reconstruction has stopped changing, which is what convergence looks like from the outside: the energy has flattened and the tokens have settled at a fixed point.
| Dataset | Split | GraphConsis | CAREGNN | PC-GNN | BWGNN | MLP | GT | ET (Ours) | |
|---|---|---|---|---|---|---|---|---|---|
| Macro-F1 | Yelp | 1% | 56.8±2.8 | 62.1±1.3 | 59.8±1.4 | 61.1±0.4 | 53.9±0.2 | 61.7±0.4 | 63.0±0.6 |
| 40% | 58.7±2.0 | 63.3±0.9 | 63.0±2.3 | 71.0±0.9 | 57.5±0.8 | 68.7±0.4 | 71.5±0.1 | ||
| Amazon | 1% | 68.5±3.4 | 68.7±1.6 | 79.8±5.6 | 90.9±0.7 | 74.6±1.2 | 88.6±0.5 | 89.3±0.7 | |
| 40% | 75.1±3.2 | 86.3±1.7 | 89.5±0.7 | 92.2±0.4 | 79.1±1.2 | 91.7±0.8 | 92.8±0.3 | ||
| T-Finance | 1% | 71.7 | 73.3 | 62.0 | 84.8 | 61.0 | 81.5 | 85.1±1.0 | |
| 40% | 73.4 | 77.5 | 63.1 | 86.8 | 70.5 | 83.6 | 88.2±1.0 | ||
| T-Social | 1% | 52.4 | 55.8 | 51.1 | 75.9 | 50.0 | 64.3 | 79.1±0.7 | |
| 40% | 56.5 | 56.2 | 52.1 | 83.9 | 50.3 | 68.2 | 83.5±0.4 | ||
| AUC | Yelp | 1% | 66.4±3.4 | 75.0±3.8 | 75.4±0.9 | 72.0±0.5 | 59.8±0.4 | 72.5±0.6 | 73.2±0.8 |
| 40% | 69.8±3.0 | 76.1±2.9 | 79.8±0.1 | 84.0±0.9 | 66.5±1.0 | 81.9±0.5 | 84.9±0.3 | ||
| Amazon | 1% | 74.1±3.5 | 88.6±3.5 | 90.4±2.0 | 89.4±0.3 | 83.6±1.7 | 89.0±1.2 | 91.9±1.0 | |
| 40% | 87.4±3.3 | 90.5±1.6 | 95.8±0.1 | 98.0±0.4 | 89.8±1.0 | 95.4±0.6 | 97.3±0.4 | ||
| T-Finance | 1% | 90.2 | 90.5 | 90.7 | 91.1 | 82.9 | 90.0 | 92.8±1.1 | |
| 40% | 91.4 | 92.1 | 91.2 | 94.3 | 87.1 | 88.2 | 95.0±3.0 | ||
| T-Social | 1% | 65.2 | 71.2 | 59.8 | 88.0 | 56.3 | 81.4 | 91.9±0.6 | |
| 40% | 71.2 | 71.8 | 68.4 | 95.2 | 56.9 | 82.5 | 93.9±0.2 |
Mean and standard deviation over 5 runs with different train/dev/test splits, following the protocol of Tang et al. Standard deviations are shown only where prior work reports them. Bold marks the best result in each row.
Baselines. GraphConsis (Liu et al., SIGIR 2020) · CARE-GNN (Dou et al., CIKM 2020) · PC-GNN (Liu et al., WWW 2021) · BWGNN (Tang et al., 2022) · GT (Dwivedi & Bresson, 2020). MLP is a plain multilayer perceptron with no graph structure.
| Method | PROTEINS | NCI1 | NCI109 | DD | ENZYMES | MUTAG | MUTAGENICITY | FRANKENSTEIN |
|---|---|---|---|---|---|---|---|---|
| WKPI (kmeans) | 78.5±0.4 ▼ 6.4 | 87.5±0.5 | 85.9±0.4 ▼ 1.5 | 82.0±0.5 ▼ 13.7 | – | 85.8±2.5 ▼ 14.2 | – | – |
| WKPI (kcenters) | 75.2±0.4 ▼ 9.7 | 84.5±0.5 ▼ 3.0 | 87.4±0.3 | 80.3±0.4 ▼ 15.4 | – | 88.3±2.6 ▼ 11.7 | – | – |
| Spec-GN | – | 84.8±1.6 ▼ 2.7 | 83.6±0.8 ▼ 3.8 | – | 72.5±5.8 ▼ 5.9 | – | – | – |
| Norm-GN | – | 84.9±1.7 ▼ 2.6 | 83.5±1.3 ▼ 3.9 | – | 73.3±8.0 ▼ 5.1 | – | – | – |
| GWL-WL | 75.8±0.6 ▼ 9.1 | – | – | – | 71.3±1.1 ▼ 7.1 | – | – | 78.9±0.3 |
| HGP-SL | 84.9±1.6 | 78.5±0.8 ▼ 9.1 | 80.7±1.2 ▼ 6.7 | 81.0±1.3 ▼ 14.7 | 68.8±2.1 ▼ 9.6 | – | 82.2±0.6 | – |
| DSGCN | 77.3±0.4 ▼ 7.6 | – | – | – | 78.4±0.6 | – | – | – |
| U2GNN | 80.0±3.2 ▼ 4.9 | – | – | 95.7±1.9 | – | 88.5±7.1 ▼ 11.5 | – | – |
| NDP | 73.4±3.1 ▼ 11.5 | 74.2±1.7 ▼ 13.3 | – | 72.8±5.4 ▼ 22.9 | 44.5±7.4 ▼ 34.9 | 87.9±5.7 ▼ 12.1 | 77.9±1.4 ▼ 4.3 | – |
| ASAP | 74.2±0.8 ▼ 10.7 | 71.5±0.4 ▼ 16.0 | 70.1±0.6 ▼ 17.3 | 76.9±0.7 ▼ 18.8 | – | – | – | 66.3±0.5 ▼ 12.6 |
| EvoG | – | – | – | – | 55.7 ▼ 22.7 | 100.0 | – | – |
| ET (Ours) | 90.3±0.7 ▲ 5.4 | 90.1±0.1 ▲ 2.6 | 90.5±0.1 ▲ 3.1 | 95.9±0.8 ▲ 0.2 | 99.8 ▲ 21.4 | 96.6±0.2 ▼ 3.4 | 98.7±0.1 ▲ 16.5 | 99.8±0.1 ▲ 20.9 |
Mean and standard deviation from 100 runs of 10-fold cross validation, following the TUDataset protocol. Entries unavailable in prior work are marked –. The shaded cell in each column is the strongest published baseline for that dataset, and every other entry carries its difference against it: ▲ above, ▼ below.
Baselines. WKPI (Zhao & Wang, NeurIPS 2019) · Spec-GN / Norm-GN (Yang et al., ICML 2022) · GWL-WL (Orsini et al., IJCAI 2015) · HGP-SL (Zhang et al., TKDE 2021) · DSGCN (Balcilar et al., 2020) · U2GNN (Nguyen et al., WWW 2022) · NDP (Bianchi et al., TNNLS 2020) · ASAP (Ranjan et al., 2019) · EvoG (Domingue et al., WNYISPW 2019).
The Associative Memory foundations that ET is built on are surveyed in Modern Methods in Associative Memory, and the same energy-based perspective is applied to generative models in Memorization to Generalization: Emergence of Diffusion Models from Associative Memory and Language Diffusion Models are Associative Memories Capable of Retrieving Unseen Data. For background, see my blog post on energy-based modeling.
@inproceedings{HooverET23,
  author = {Hoover, Benjamin and Liang, Yuchen and Pham, Bao and Panda, Rameswar and Strobelt Hendrik and Chau, Duen Horng and Zaki, Mohammed and Krotov, Dmitry},
  booktitle = {Advances in Neural Information Processing Systems},
  doi = {10.52202/075280-1197},
  editor = {A. Oh and T. Naumann and A. Globerson and K. Saenko and M. Hardt and S. Levine},
  pages = {27532--27559},
  publisher = {Curran Associates, Inc.},
  title = {Energy Transformer},
  url = {https://proceedings.neurips.cc/paper_files/paper/2023/file/57a9b97477b67936298489e3c1417b0a-Paper-Conference.pdf},
  volume = {36},
  year = {2023}
}